HIVE Multiprocessor
Patent-pending multiprocessor design with dynamic instruction dispatch around pipeline stalls
Project Overview
The HIVE Multiprocessor is a patent-pending CPU architecture built around RAPID (Real-time Adaptive Pipeline Instruction Dispatch), a mechanism for routing instructions around pipeline stalls.
It targets two bottlenecks in conventional processors: single-core performance limits and pipeline stalls that waste execution cycles. By splitting the traditional pipeline into independent front-end instruction fetchers and back-end execution units, HIVE routes each instruction to whichever execution unit is free, so a stall in one unit doesn't hold up the others.
The architecture introduces a novel "Fill Check" pipeline stage that intelligently monitors backend buffer availability, allowing front-ends to route instructions to any available execution unit. This clustering approach, termed "HIVE" to distinguish it from traditional cores, represents a paradigm shift in processor design with applications spanning data centers to portable electronics.
Revolutionary Architecture Design
The HIVE Multiprocessor introduces two fundamental innovations to conventional processor design:
Split Pipeline Architecture: Separates instruction fetching (front-end) from execution (back-end), allowing multiple instances of each component
RAPID Dispatch System: Dynamic instruction routing mechanism that optimizes resource allocation based on real-time availability
Fill Check Stage: Novel pipeline stage that monitors backend buffer status to prevent stalls
Multi-Frontend to Multi-Backend Routing: Independent front-ends can dispatch to any available back-end execution unit
This design eliminates the traditional one-to-one mapping between instruction fetch and execution, creating a more flexible and efficient processing environment.
Conventional vs. HIVE
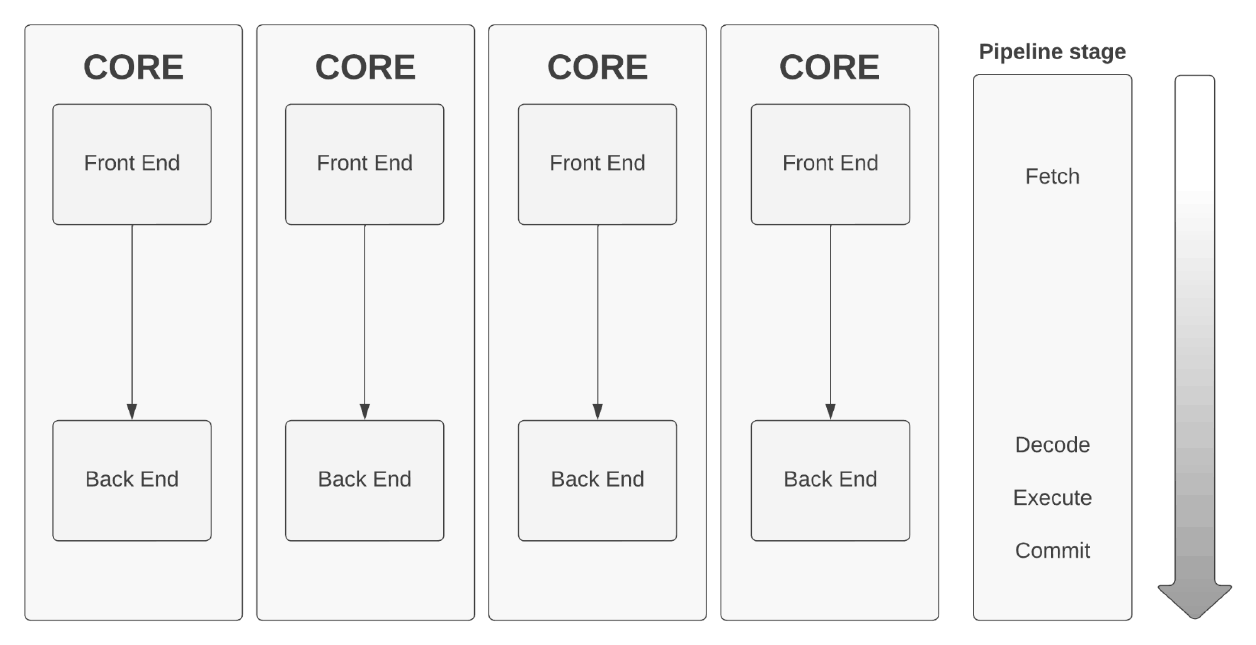
FIG. 1: a conventional multicore processor. Each core welds one front end (fetch, predecode) to one back end (decode, execute, commit), so a thread can only use its own core's execution resources.
Technical Innovation: RAPID Mechanism
RAPID (Real-time Adaptive Pipeline Instruction Dispatch) represents the core innovation of the HIVE architecture:
Dynamic Load Balancing: Automatically distributes instructions across available execution units
Pipeline Stall Reduction: Prevents bottlenecks by routing around full buffers
Resource Optimization: Maximizes utilization of execution units through intelligent dispatch
Adaptive Routing: Real-time decision making based on current system state
The Fill Check stage continuously monitors backend availability, enabling instant redirection when buffers become full, thus maintaining optimal instruction throughput.
Inside RAPID
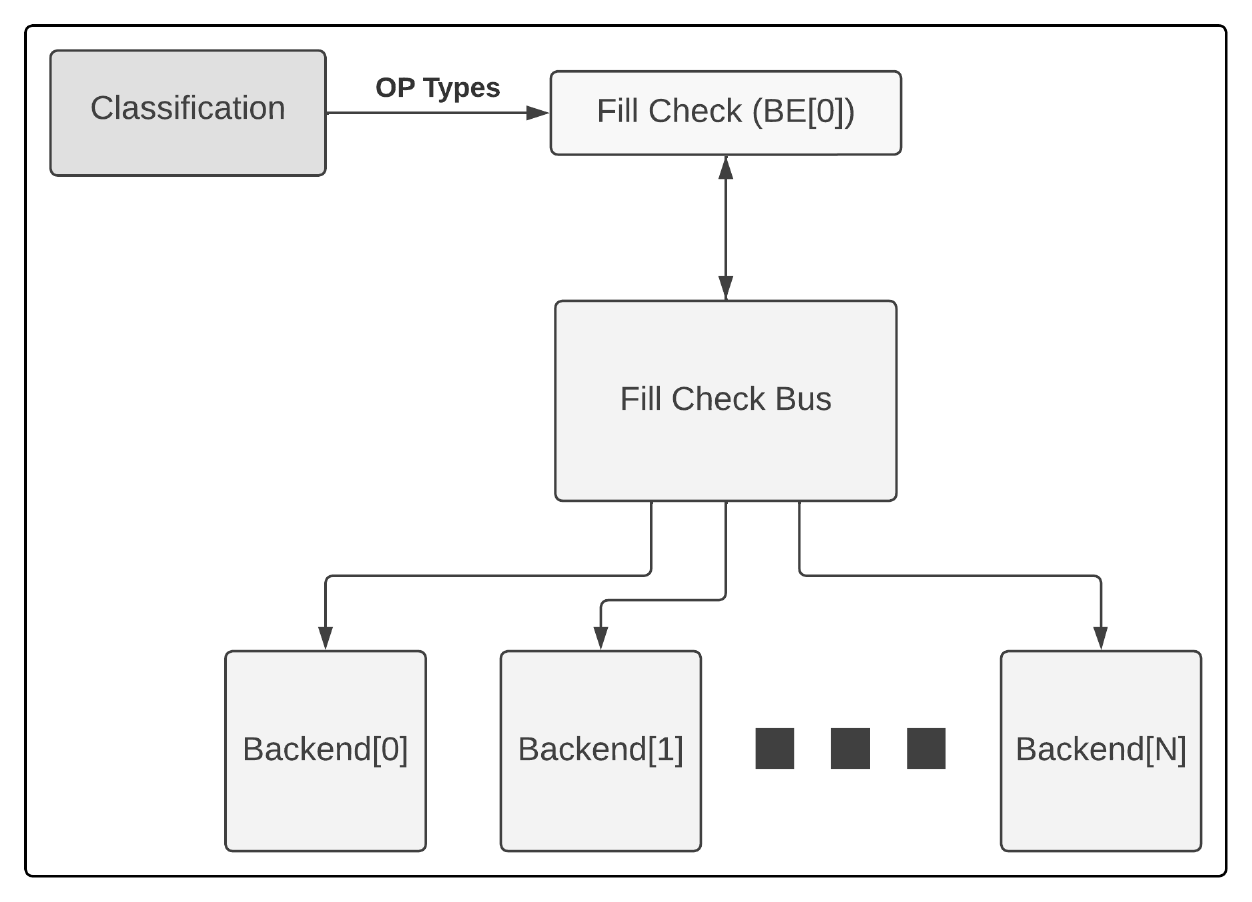
FIG. 3: RAPID inside the front end. A Classification stage tags each instruction's operation types, and the Fill Check stage uses the Fill Check Bus to poll Backend[0] through Backend[N] for room.
Making the split work
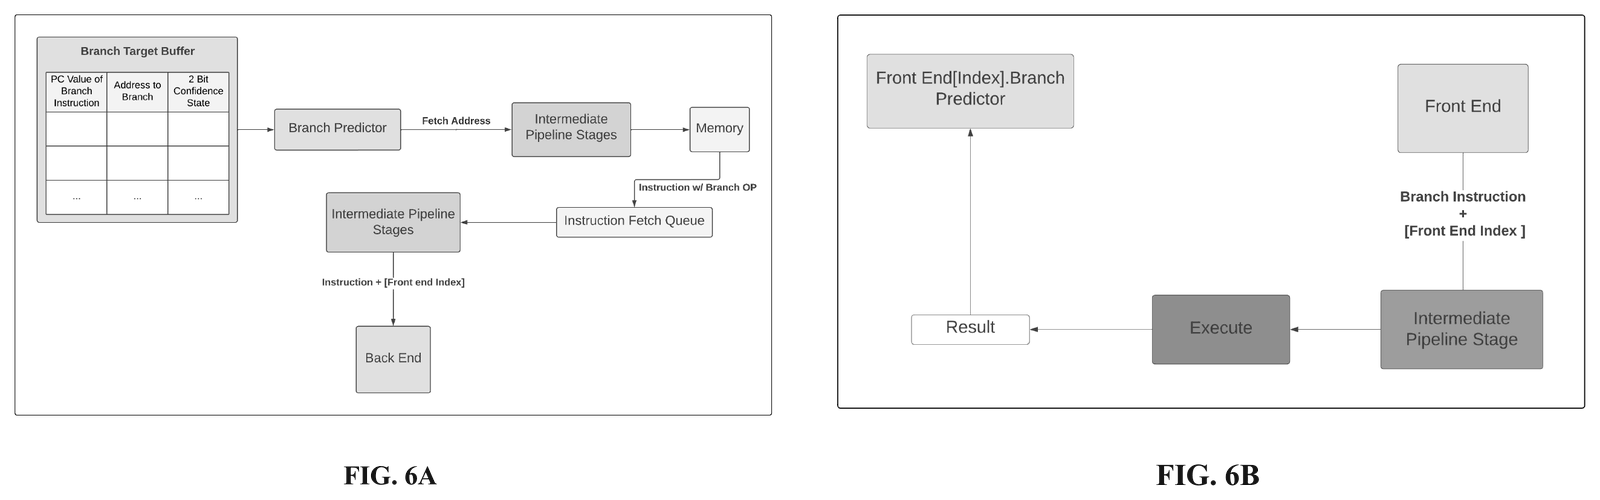
FIG. 6A and 6B: branch prediction across the split. A branch leaves the front end tagged with its front-end index, and after it executes in a back end the result is routed back to that front end's branch predictor.
Register renaming
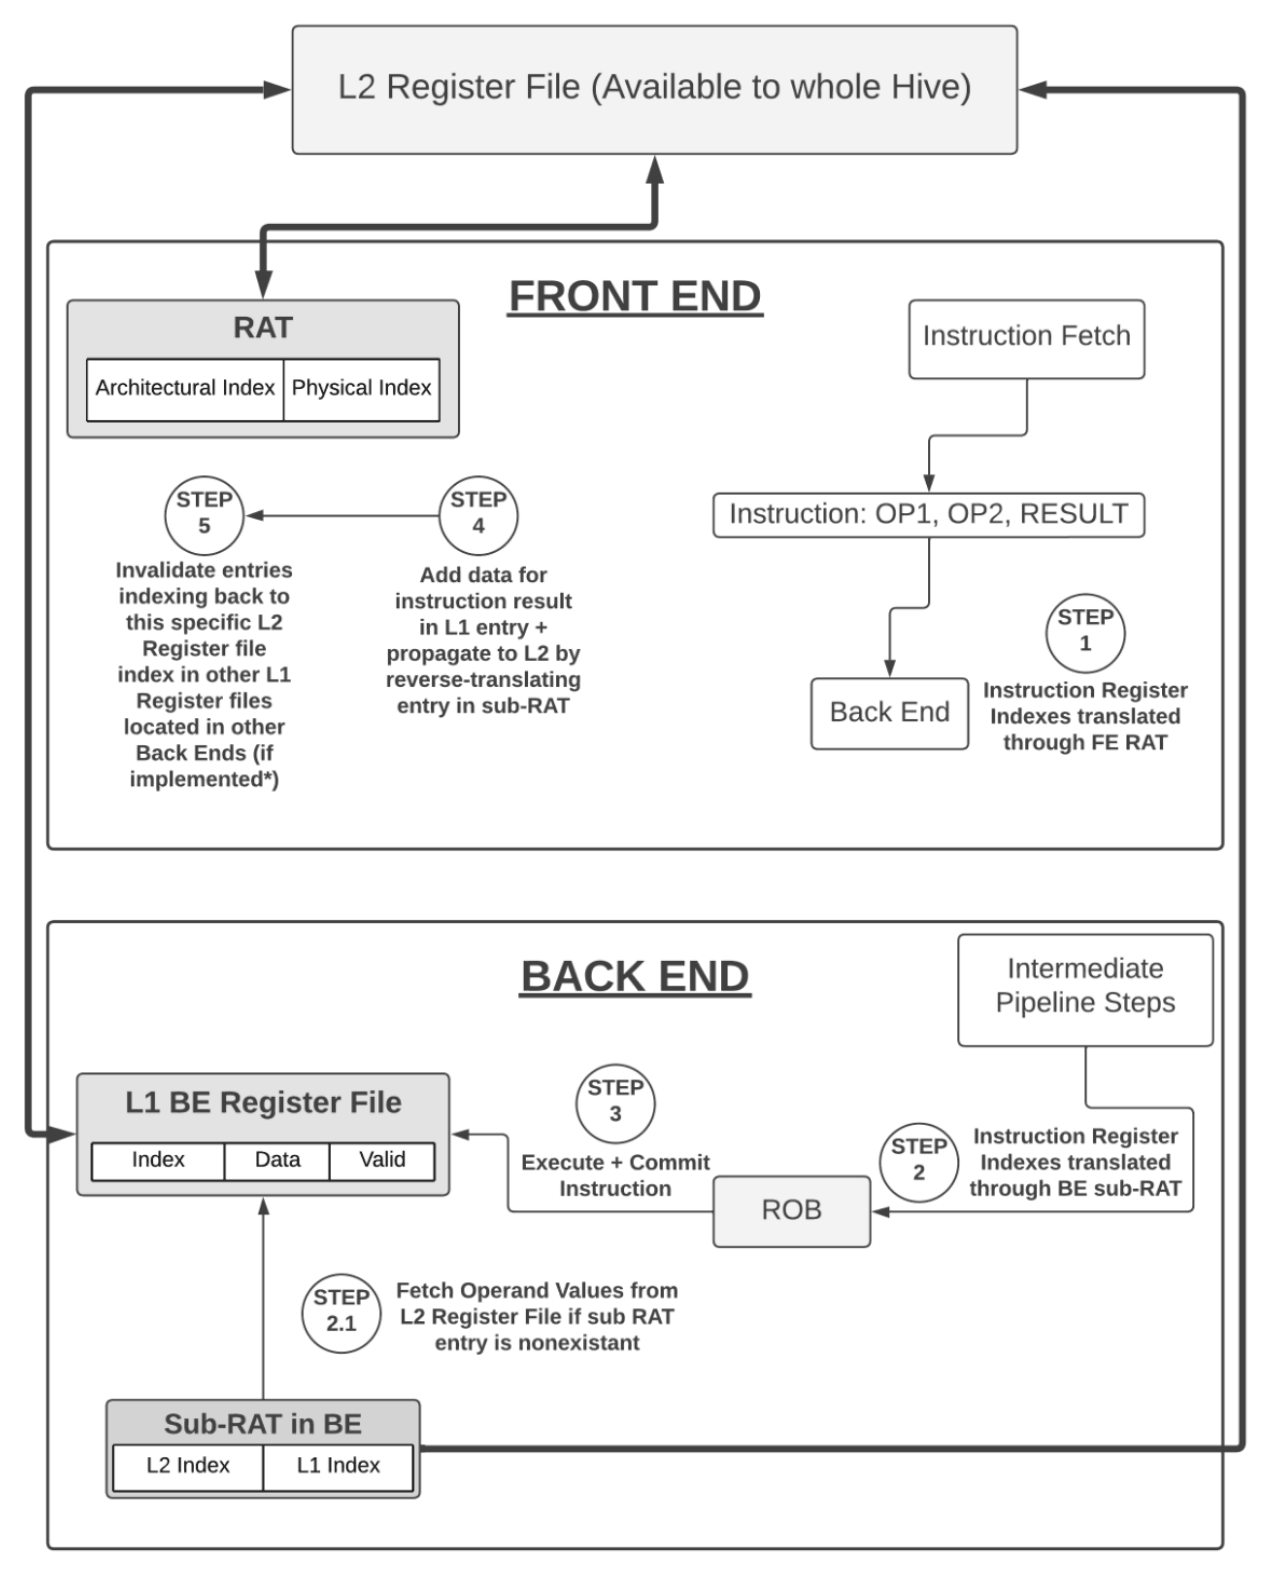
FIG. 9: two-level register renaming. Each front end's RAT maps architectural registers to a shared L2 register file; each back end's sub-RAT maps those to its private L1 register file, fetching from L2 on a miss, writing results back to L2, and invalidating stale copies in other back ends.
Patent Status
Patent pending (application #63533037).
Skills & Technologies
Links
Project Info
January 2024 - September 2024
Patent Pending